Python PDF Table Extraction: Camelot vs. Tabula vs. PDF Plumber
- Authors
- Published on
- Published on
In this exhilarating exploration, the NeuralNine crew dives headfirst into the thrilling world of parsing tables from PDFs using Python. Buckle up as they pit Camelot, Tabula, PDF Plumber, and the unique LLM Whisperer against each other in a high-octane showdown. Camelot, the first contender, promises table extraction prowess but falters when faced with the intricate structure of PDFs, leaving the team yearning for more precision.
Next up is Tabula, a Java-based heavyweight in the ring. With its allure of multiple tables and lattice/stream extraction, Tabula seems like a formidable opponent. However, as the dust settles, it becomes evident that Tabula struggles to deliver the knockout blow, leaving the team searching for a more effective solution. Enter PDF Plumber, a precision-focused contender known for its accuracy and customizability.
With PDF Plumber in their corner, the team embarks on a quest for the ultimate table extraction solution. Armed with a slew of customizable settings, PDF Plumber manages to extract tables with more finesse, offering a glimmer of hope in the chaotic world of PDF parsing. But just when it seems like the battle is won, a wildcard enters the arena - LLM Whisperer. Sponsored by LLM Whisperer and Unra, this unconventional approach introduces a new dimension to the table extraction game.
LLM Whisperer, with its unique API key requirement, presents a tantalizing prospect for those seeking a cutting-edge solution. As the team delves into the realm of LLM Whisperer, the stakes are higher than ever. Will this underdog emerge victorious, or will the tried-and-tested contenders reign supreme? Only time will tell in this adrenaline-fueled quest for the ultimate PDF table extraction champion.
Image copyright Youtube
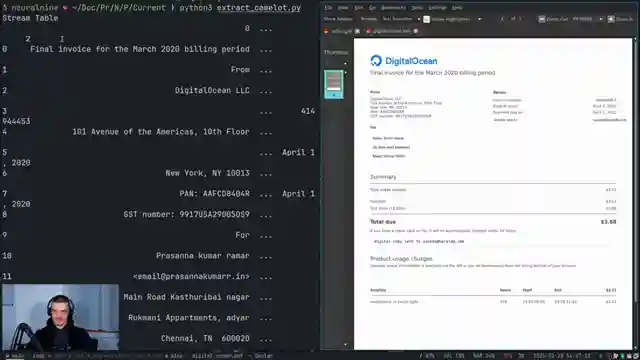
Image copyright Youtube
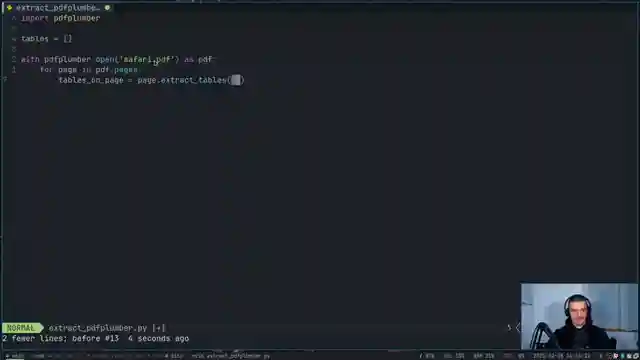
Image copyright Youtube
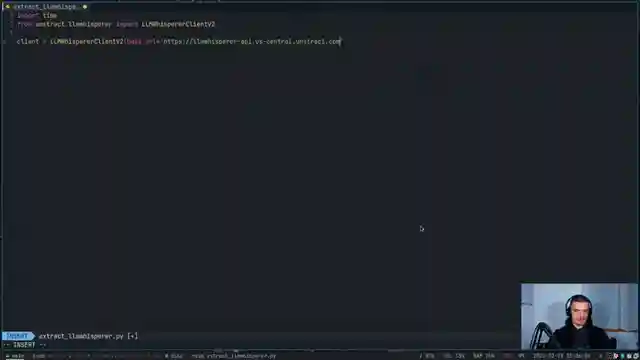
Image copyright Youtube
Watch Python Libraries to Extract Tables from PDFs on Youtube
Viewer Reactions for Python Libraries to Extract Tables from PDFs
Tabula (Java web app version) works best for extracting tables
Python-based PDF table extractors had unpredictable and inaccurate output
Docker was useful for running Tabula Java web app on Ubuntu 24.04
Suggestion for intro automation to show results before watching
Request for more complex table examples like financial statements
Mention of ML-based chips extracting data from invoices for 20 years
Recommendation for using chat GPT directly with pypdf
Request for a video on enlarging VRAM of GPU
Related Articles
Nanet's OCR Small: Advanced Features for Specialized Document Processing
Nanet's OCR Small, based on Quen 2.5VL, offers advanced features like equation recognition, signature detection, and table extraction. This model excels in specialized OCR tasks, showcasing superior performance and versatility in document processing.

Enhancing AI Observability with Langmith and Linesmith
Langmith, part of Lang Chain, offers AI observability for LMS and agents. Linesmith simplifies setup, tracks activities, and provides valuable insights with minimal effort. Obtain an API key for access to tracing projects and detailed information. Enhance observability by making functions traceable and utilizing filtering options in Linesmith.

Alibaba's Juan 2.1 AI Model: Ethics of AI-Generated Adult Content
Alibaba's Juan 2.1 AI model sparks global debate as it's swiftly used for adult content, raising ethical concerns about privacy and consent.

Revolutionizing AI: Gpark's Super Agent vs. Byte Dance's Dream Actor M1
Gpark's Super Agent and Byte Dance's Dream Actor M1 revolutionize AI technology. Super Agent offers phone call capabilities for tasks like reservations, while Dream Actor M1 animates images into dynamic videos. Both showcase AI's potential in everyday tasks and image animation, but ethical concerns arise.